shipwithmuse

Entries matching “ollama”

14 builds · page 1 of 1

ollama

@ollama

Using @AIatMeta's Muse Glimmer all locally to process personal monthly credit card statements. Your data belongs to you! Try different agent tasks using your favorite apps / harnesses with Ollama.

X post · Local & open models★ Pick· ♥ 345

Local credit card statement analysis with Glimmer

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

O

ollama.com

ollama.com

Ollama shipped Muse Glimmer on day one: `ollama run muse-glimmer`, plus a muse-glimmer:30b-mlx tag for Apple Silicon that Ollama says runs 1.5–1.8x faster with DFlash.

Site · Local & open models

Muse Glimmer in the Ollama library

H

holaclaw.ai

holaclaw.ai

HolaClaw's tutorial for running Muse Glimmer 30B behind OpenClaw on a Mac, with hardware requirements and llama.cpp and Ollama setup.

Resource · Local & open models

Run OpenClaw with Muse Glimmer locally

@schererstefan

@schererstefan

glimmer-cli is a local TypeScript CLI for Muse Glimmer 30B and Muse Spark 1.2 via Ollama, with stubbed tools and a reproducible tool-use eval harness.

GitHub · Local & open models

glimmer-cli for Muse Glimmer and Spark

@emonibnmustafa

@emonibnmustafa

A local translation gateway and profile manager that plugs Meta Muse Spark (or DeepSeek, Groq, Ollama) into OpenAI Codex and ChatGPT Desktop, translating tool calls and SSE streams, with a one-command switch between providers.

GitHub · Coding & dev tools

AnyCodex: Muse Spark inside Codex Desktop

M

research.meta.ai

research.meta.ai

Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models

Introducing Muse Glimmer

Paolo Rosson

@redp314

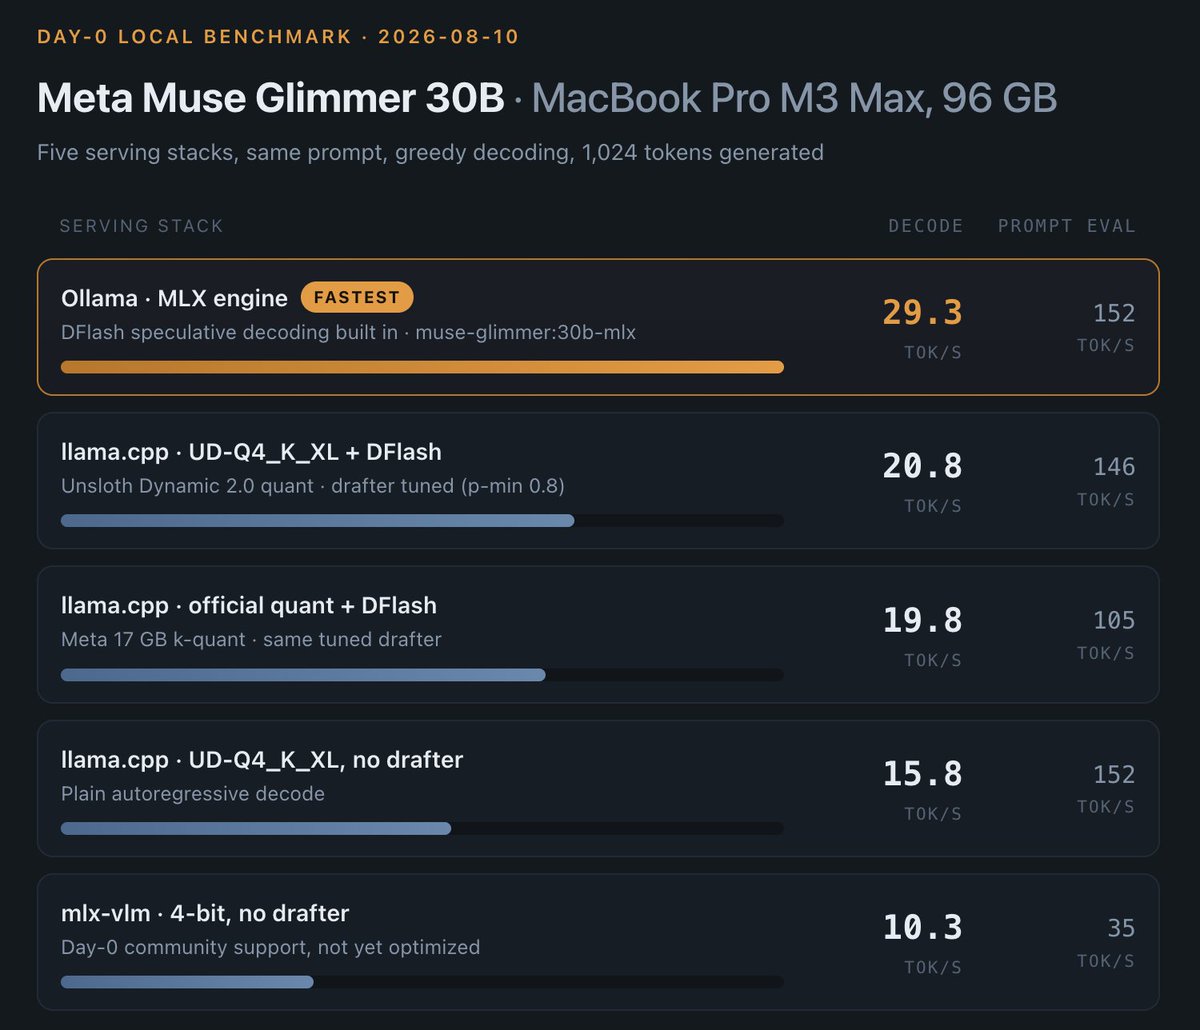
Got Meta's new Muse Glimmer 30B running on my MacBook (M3 Max, 96GG) and tested the serving options available so far. Fastest right now: Ollama's MLX engine (DFlash included) at ~29 tok/s. Tuned llama.cpp: ~21. Raw mlx-vlm: ~10, not optimized yet. Numbers below if you're

X post · Local & open models★ Pick· ♥ 44

Glimmer serving shootout on an M3 Max

U

ogbrien

u/ogbrien

I think a lot of people are boxing Muse in as “Hermes for normies.” My guess is Meta intentionally keeps the deeper capabilities out of sight because the target audience does not want a complicated Hermes/Grok Bot-style setup. They aren't trying to capture the nerdy Hermes using market, they want this to be an AI agent for normies but they don't limit it as such. What it advertises its for is far from what it actually can do with very little work. But Muse gets much more interesting once you stop thinking of its VM as the whole system. I joined the Muse VM to my Tailscale network, gave it SSH access to a restricted user on my home Ubuntu box, and now it can run commands and browser automation through hardware I already own. I figured out Muse can do this because I asked it if it had a Tailscale skill and it said it did, then after a series of "proceed" replies, it set it up for me outside of the parts where I had to join it. At that point, Muse stops being a “shopping assistant” and starts looking more like a control plane for your own infrastructure. With Tailscale + SSH/API access, it can potentially: • Manage Docker, VMs, NAS, Proxmox, and homelab services • Pull repos,

Reddit post · Agents & automation★ Pick

Muse as a control plane for a homelab via Tailscale

ollama

@ollama

Ollama already support the Muse Code harness out of the box? You can try it with models via Ollama (local and cloud): ollama launch muse

X post · Coding & dev tools· ♥ 220

Muse Code harness with Ollama models

ollama

@ollama

Muse Glimmer is now available to run with Ollama. Available today via Ollama’s MLX engine with state-of-the-art-performance on Apple Silicon, Muse Glimmer can power Claude Code, Codex, and more always-on local agent workflows natively using Ollama. Additional support and

X post · Local & open models· ♥ 1.3K

Muse Glimmer on Ollama's MLX engine

@kenhuangus

@kenhuangus

Files from a working DeepSeek Harness session against Muse Glimmer 30B served by Ollama on a DGX Spark, including a sample agentic security project that queries an AST call graph.

@nano-muse

@nano-muse

nanoMuse is an open-source personal AI agent inspired by Meta Muse that runs on Android with a shell, browser, MCP, skills and scheduled tasks, and can be pointed at DeepSeek, OpenAI or Ollama models.

GitHub · Agents & automation

nanoMuse open-source personal agent