
señor jingu 🦧
@jingusucks
holy 🐐 @muse just lowballed 50 ppl on marketplace until it found a brand new m5 pro 48gb/2tb macbook pro for $2500 ama
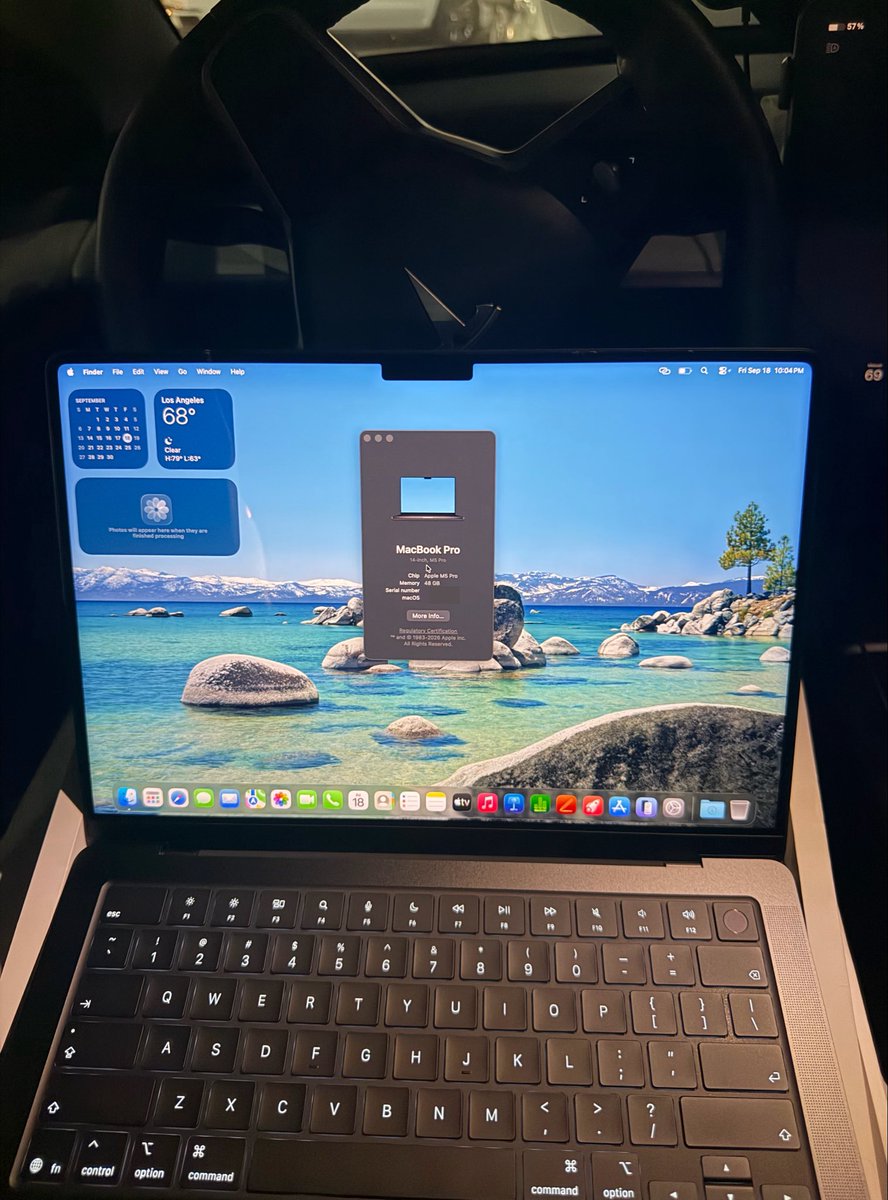
X post · Errands & personal agent★ Pick· ♥ 1.4K
7 builds · page 1 of 1
señor jingu 🦧
@jingusucks
holy 🐐 @muse just lowballed 50 ppl on marketplace until it found a brand new m5 pro 48gb/2tb macbook pro for $2500 ama
X post · Errands & personal agent★ Pick· ♥ 1.4K
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
A reproducible record of running the 17GB Muse Glimmer 30B GGUF with llama.cpp and Metal on a 24GB M4 Pro MacBook Pro, with notes on mistakes, fixes and how local inference works.
GitHub · Local & open models
This repo documents running Muse Glimmer 30B locally on an M4 Max MacBook via llama.cpp, benchmarking it with and without speculative decoding, and wiring it into Claude Code through LiteLLM for fully offline coding.
GitHub · Local & open models

Paolo Rosson
@redp314
Got Meta's new Muse Glimmer 30B running on my MacBook (M3 Max, 96GG) and tested the serving options available so far. Fastest right now: Ollama's MLX engine (DFlash included) at ~29 tok/s. Tuned llama.cpp: ~21. Raw mlx-vlm: ~10, not optimized yet. Numbers below if you're
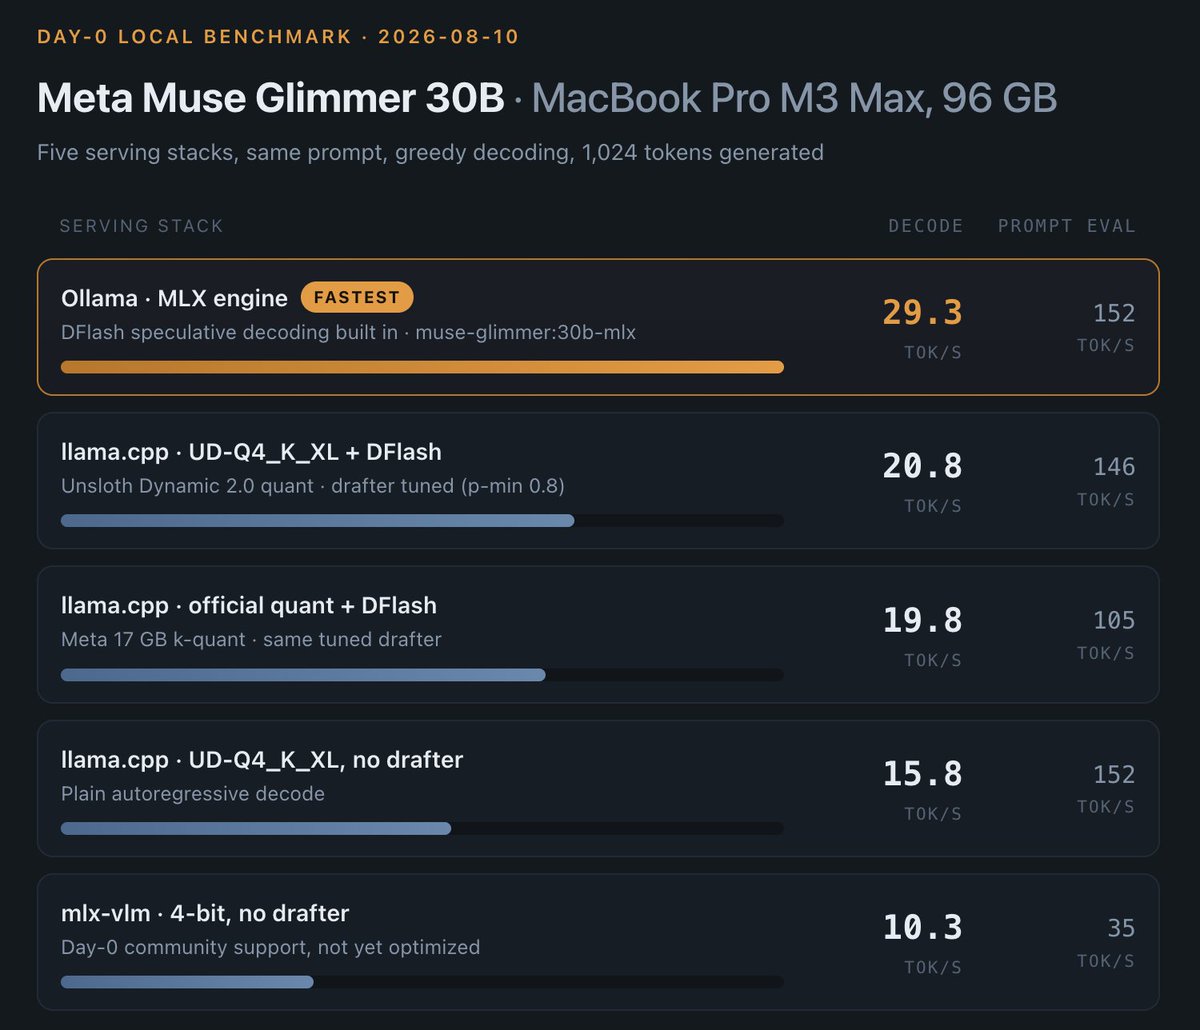
X post · Local & open models★ Pick· ♥ 44

TimDarcet
@TimDarcet
Happy to release ✨ Muse Glimmer ✨ - level ~= Qwen 3.6-27B - Apache 2 - 30B dense - quantized to run in 17GB - quant + spec dec => 50 tok/s on macbook m5 max, interactive, smooth Enjoy!
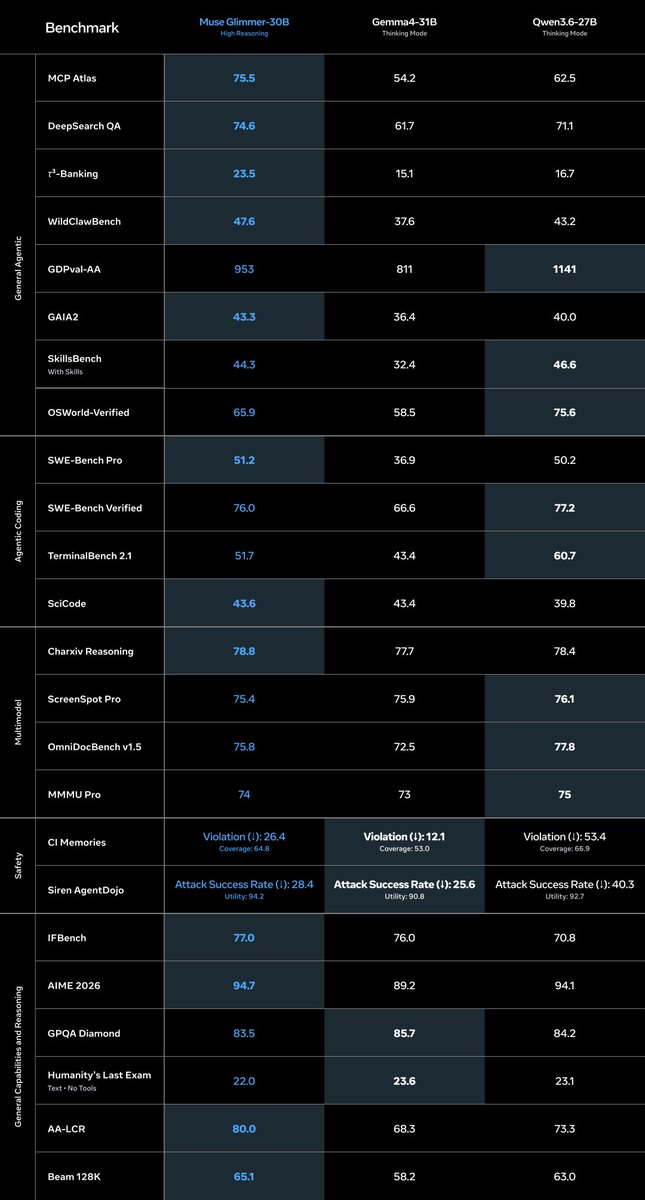
X post · Local & open models· ♥ 74
Hi all, I'm a newbie and trying to assess the performance of some LLMs I'm running locally via oMLX on my MacBook Pro M5pro CPU 15 cores (5 Super and 10 Performance), GPU 16 cores and 48 GB of LPDDR5 RAM. I asked chatGPT guidance to run some tests and check whether the DFlash-based drafter Muse-Glimmer-30B-Assistant might somewhat speedup the base model Muse-Glimmer-30B-4bit. The results show no or negligible improvement with active DFlash acceleration (speedup between 0.90% and 1.16%). The test was structured with three different prompts fed to both the baseline and the dflash-capable model profiles: Technical prose; Python code; Structured JSON a cap of 2048 tokens, no cache, temperature=0. Each inference was repeated three times. Anyone have similar experience? can we simply dump the Assistant as not useful in this hw/sw configuration?
Reddit post · Local & open models
Scripts that run Muse-Glimmer-30B with vision and tool calling on a 32GB M2 MacBook Pro via llama.cpp and Metal, without admin or sudo access, pulling Meta's official GGUFs.
GitHub · Local & open models· ★ 1


 ChatForm
 Tgmlabs