Curated with by@mohithkumar808

Entries matching “internal-eval”

AI at Meta

@AIatMeta

Today we’re also previewing WildArtifactBench, an internal evaluation framework designed to assess agents on complex, real-world tasks across diverse deliverable formats. By using win rates and Elo scores from human and agentic preference judges rather than strict ground-truth
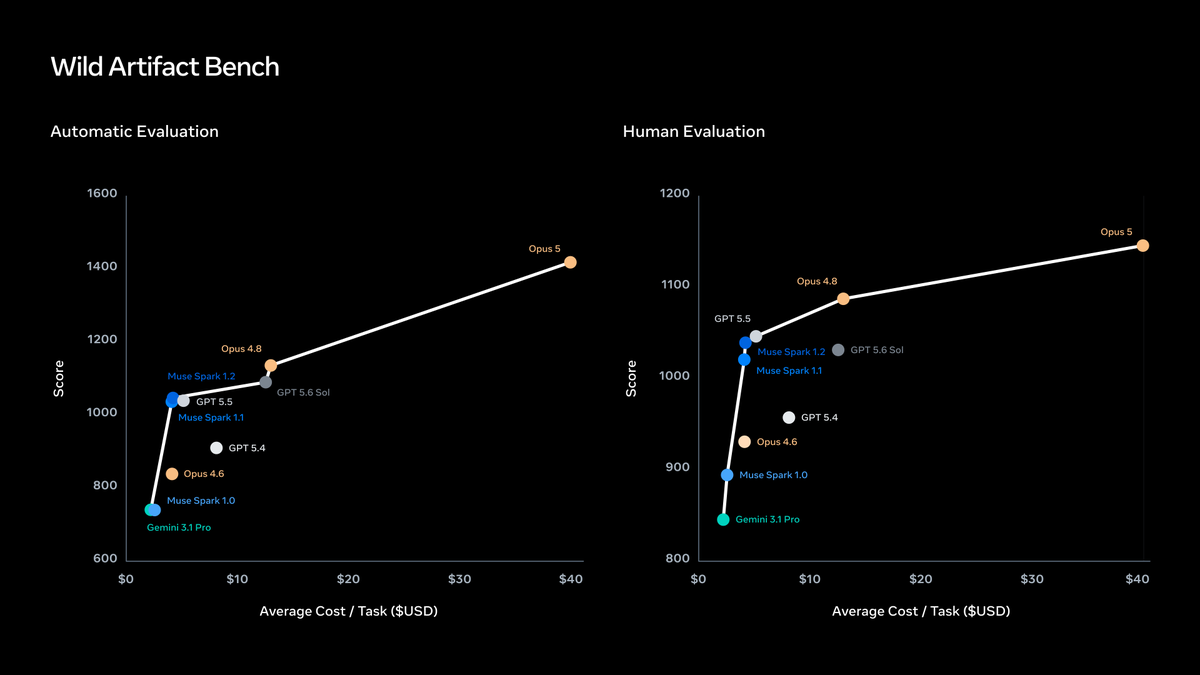
X post · Benchmarks & research★ Pick· ♥ 637
WildArtifactBench agent eval preview

trycodus.com

trycodus.com

Codus reads the three benchmark charts Meta published for Muse Code and notes Claude Opus 5 wins all three, including Meta's own internal eval.

Resource · Benchmarks & research

What Meta's Muse Code benchmarks actually say

2 builds · page 1 of 1

Want more AI builds?artificialbuilds.com