
A measured deployment report of Muse Glimmer 30B NVFP4 with DFlash on a single Dell Pro Max GB10, where it posted top vision and SRE-ops scores but failed five deployment gates against DeepSeek V4 Flash.
GitHub · Local & open models
8 builds · page 1 of 1
A measured deployment report of Muse Glimmer 30B NVFP4 with DFlash on a single Dell Pro Max GB10, where it posted top vision and SRE-ops scores but failed five deployment gates against DeepSeek V4 Flash.
GitHub · Local & open models
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
A pinned llama.cpp recipe for Muse Glimmer 30B on one NVIDIA GB10 that verifies Meta's official GGUFs by SHA-256 and reproduces text, tool-call, coding, vision and throughput checks.
GitHub · Local & open models· ★ 1
A one-script vLLM setup that serves the roughly 19 GB NVFP4 Muse Glimmer 30B with its vision encoder kept, DFlash speculative decoding using the official drafter head, and up to 256K context on GB10, RTX 5090 or RTX PRO 6000.
GitHub · Local & open models· ★ 8
A 40-chapter book on Muser, an engine that runs Muse Glimmer on Apple Silicon Metal. It covers kquant and DFlash speculative lanes, exact KV-cache replay with kvpack, and GB10 NVFP4 prefill handed off to a Mac, with every number tied to an evidence receipt.
GitHub · Local & open models· ★ 3

filipe
@filicroval
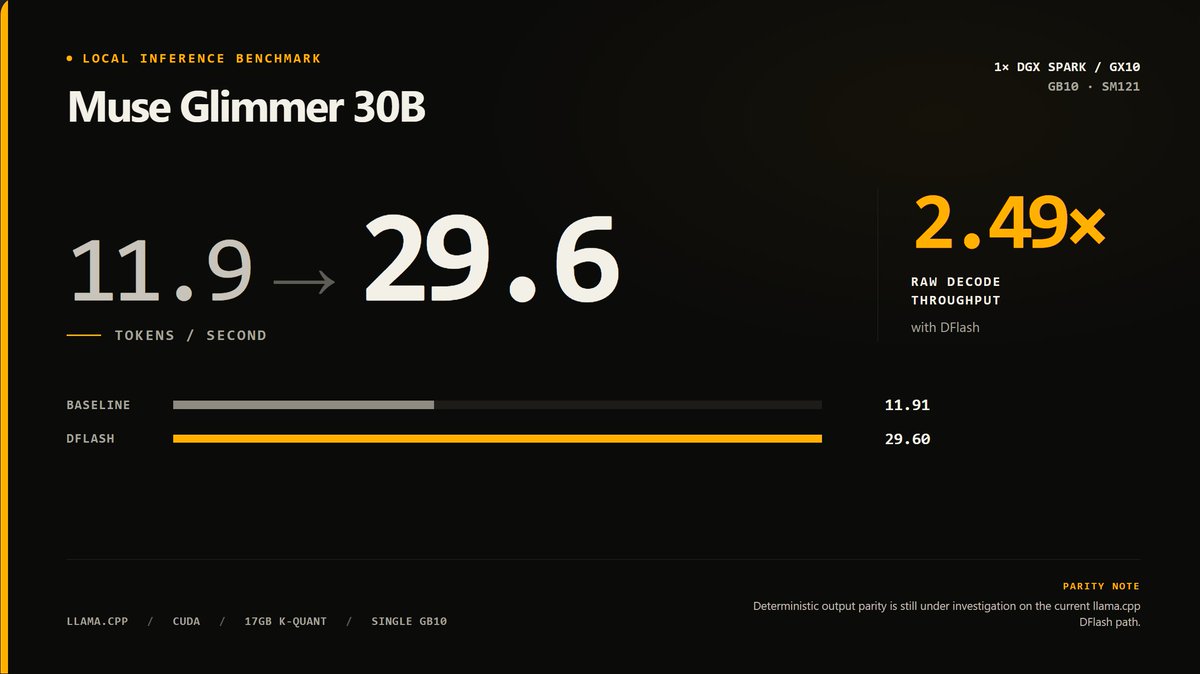
got Muse Glimmer 30B running on a single DGX Spark / GX10 at 29.6 tok/s with DFlash, up from 11.9 tok/s baseline, 2.49× raw decode throughput. packaged the whole thing into a reproducible GB10 recipe: - pinned weights + SHA-256s - llama.cpp compiled for GB10 / SM121 - baseline
X post · Local & open models· ♥ 5
Tested SGLang and vLLM launch recipes for an NVFP4 export of a Hermes-agentic fine-tune of Muse-Glimmer-30B on NVIDIA DGX Spark (GB10).
GitHub · Local & open models
muser is a standalone inference engine for Muse Glimmer 30B on Apple Silicon Metal, with an optional disaggregated lane where an NVIDIA GB10 node prefills in NVFP4 and hands the KV cache to the Mac.
GitHub · Local & open models
Reproducible native NVFP4 serving of Muse Glimmer 30B on one DGX Spark (GB10) with unmerged vLLM support: about 10.3 tok/s single-stream versus 4.2 for BF16, 52.5 tok/s at c16, and 131K context checked with needle-in-a-haystack tests.
GitHub · Local & open models


 ChatForm
 Tgmlabs