
Eric Fitzpatrick
@FITZPAE
Muse became my personal dietitian after I found that I had high blood sugar last week; really cool to have someone check in and help me plan + monitor each day!
X post · Errands & personal agent· ♥ 1
11 builds · page 1 of 1
Eric Fitzpatrick
@FITZPAE
Muse became my personal dietitian after I found that I had high blood sugar last week; really cool to have someone check in and help me plan + monitor each day!
X post · Errands & personal agent· ♥ 1
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page
HolaClaw tested Muse Glimmer on base M3 and M4 Macs: it fits in 24GB of RAM but generates at 4.3 tokens per second.
Resource · Local & open models

TimDarcet
@TimDarcet
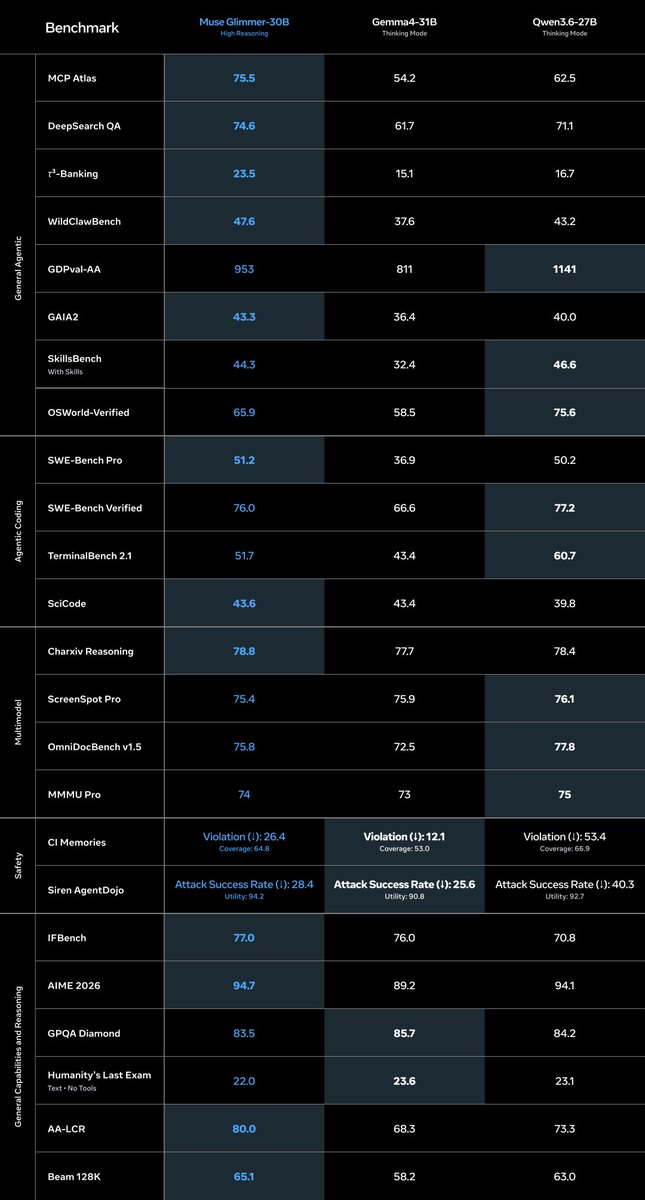
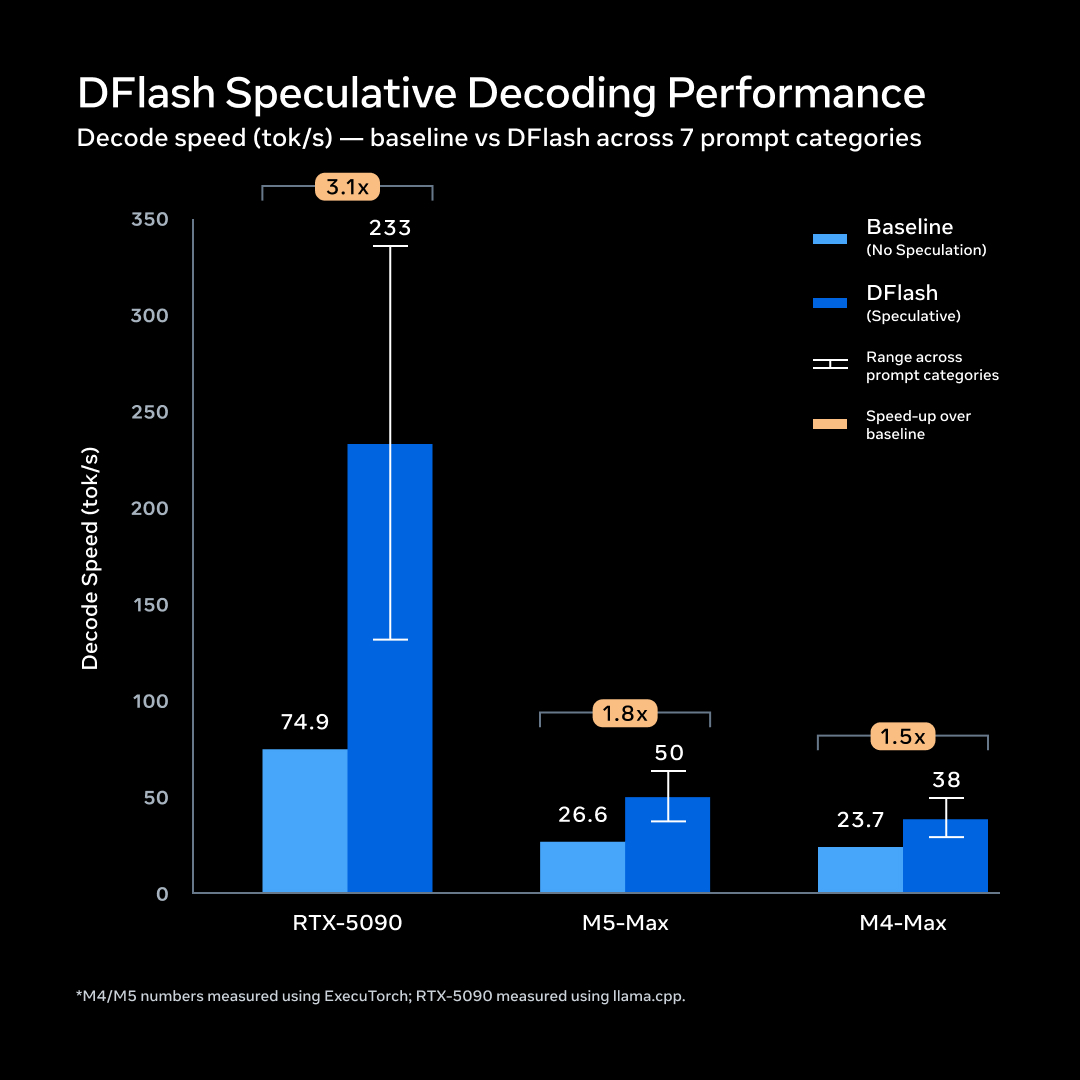
Happy to release ✨ Muse Glimmer ✨ - level ~= Qwen 3.6-27B - Apache 2 - 30B dense - quantized to run in 17GB - quant + spec dec => 50 tok/s on macbook m5 max, interactive, smooth Enjoy!
X post · Local & open models· ♥ 74
Abstract Extraordinary digs into the architecture behind Meta's pitch of an autonomous, multimodal agent that runs on-device with no cloud.
Resource · Local & open models
Meta's launch post for Muse Glimmer, an Apache 2.0 30B model for local agents that fits in ~20GB at 4-bit and runs on M4/M5 Max Macs, RTX 5090s or 24–32GB GPUs.

Resource · Local & open models

Nick Calabro
@NickCalabs
I just set up a custom connector to my self hosted fitness/nutrition tracker hours ago. I was pleased at how easy it was
X post · Connectors & MCP· ♥ 2
I noticed on the same hardware that I can get 24 x 128k contexts with muse glimmer (30b q8_0 + mmproj+dflash) only gets me 3x 256k or 6x 128k with qwen. But a straight forward analysis of the architecture suggests to me that qwen's state per token is somewhat smaller than glimmers. So it seems llama.cpp is particularly memory inefficient for the qwen arch. I presume there is an existing issue for this, but I couldn't find one. What's the deal? The extra concurrency makes a big difference in batched performance.
Reddit post · Local & open models

Arun Cherian
@ArunCherian12
Find me a credit card with 0 balance transfer fees, Muse found me a few credit union cards that offer this
X post · Errands & personal agent· ♥ 1

Cline
@cline
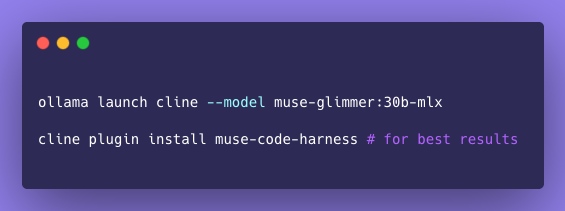
The successor to Llama is here, and Meta is revitalizing focus on open weights with their new Muse Glimmer - a leading 30B param model designed for always-on local agent use, small enough to run on a Mac or PC with a single GPU. Available in Cline using Ollama now!
X post · Local & open models· ♥ 157

AI at Meta
@AIatMeta
For a local agent to be practical, generation latency must be low enough to maintain workflow continuity. To run Muse Glimmer on consumer hardware without degrading quality, we used quantization to shrink the language model to under 20GB and a lightweight DFlash drafter model to
X post · Local & open models· ♥ 456
Been building this for a few months, mostly for myself, and it just got a proper release so figured I'd post it. It's a native GGUF inference runtime with OpenAI/Anthropic-compatible APIs and a chat UI. The whole point is one consumer NVIDIA card + lots of RAM: MoE models that don't fit in VRAM run their experts on the CPU, or split with a hot set cached on the card. It figures out what fits at startup instead of you guessing offload layer counts. Runs Qwen 3.x dense and MoE (incl. Qwen3.8-Flash-Next), DeepSeek-V4-Flash, Ling 3.0, K2-Horizon, Gemma 4, Laguna, Muse Glimmer. Image input via mmproj on the Qwen models. Also does Z-Image-Turbo image gen next to a chat model on the same card. Numbers from my laptop (5070 Ti 12 GB, 60 GB RAM): - Qwen3.8-Flash-Next IQ1_S: ~35 tok/s decode, ~475 tok/s prefill - Qwen3.8-27B IQ2_XXS: ~40 tok/s - DeepSeek-V4-Flash: 6-7 tok/s (that's basically the DRAM bandwidth limit) - Z-Image 1024x1024 in ~15 s with a 35B loaded beside it Stuff I think is neat: - Kernels are compiled at runtime by NVRTC, so no CUDA toolkit in the wheel and no nvcc. Same kernel source compiles as plain C++ for a CPU-only backend. - KV cache in f16 / q8_0 / TurboQu
Reddit post · Local & open models
 ChatForm
 Tgmlabs