Muse Glimmer 30B fine-tuned on agentic coding traces and chat distilled from Claude Fable 5, merged bf16 and drop-in for the base.
Resource · Local & open models· ♥ 3
3 builds · page 1 of 1
Muse Glimmer 30B fine-tuned on agentic coding traces and chat distilled from Claude Fable 5, merged bf16 and drop-in for the base.
Resource · Local & open models· ♥ 3
Your product
Sponsored
Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.
Shown every 12 builds · on every catalog page

wh
@nrehiew_
Muse Glimmer was trained directly logit distilled from Muse Spark. This means that there isn't a traditional 'base model' in that it was trained from the start on agentic traces. Super cool and haven't seen this approach in a while Welcome back GPT OSS
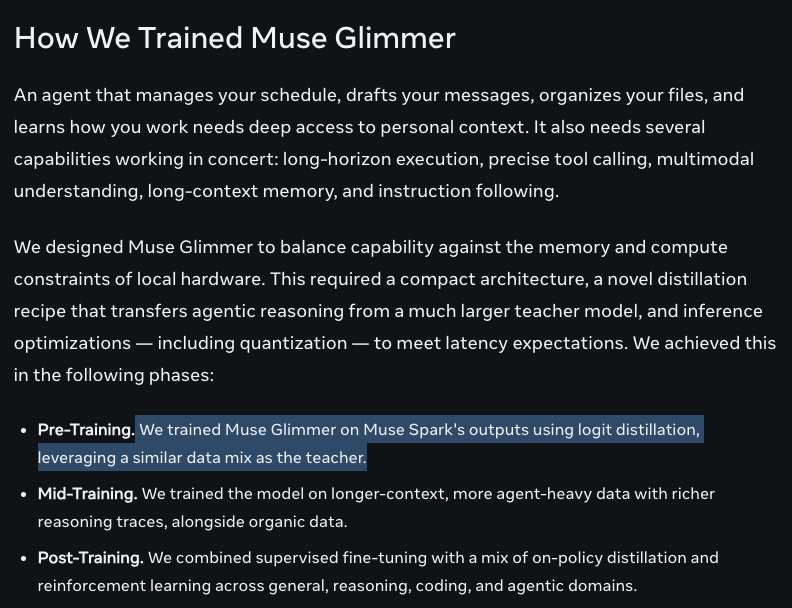
X post · Benchmarks & research· ♥ 336

elie
@eliebakouch
extremely exciting to see meta getting back into open weight models with a 30B dense first, and soon muse spark 1.2 they used knowledge distillation from muse spark, architecture wise it's similar to gemma 4 (which is llama 3 + swa (again!) + vision encoder), with scale free QK
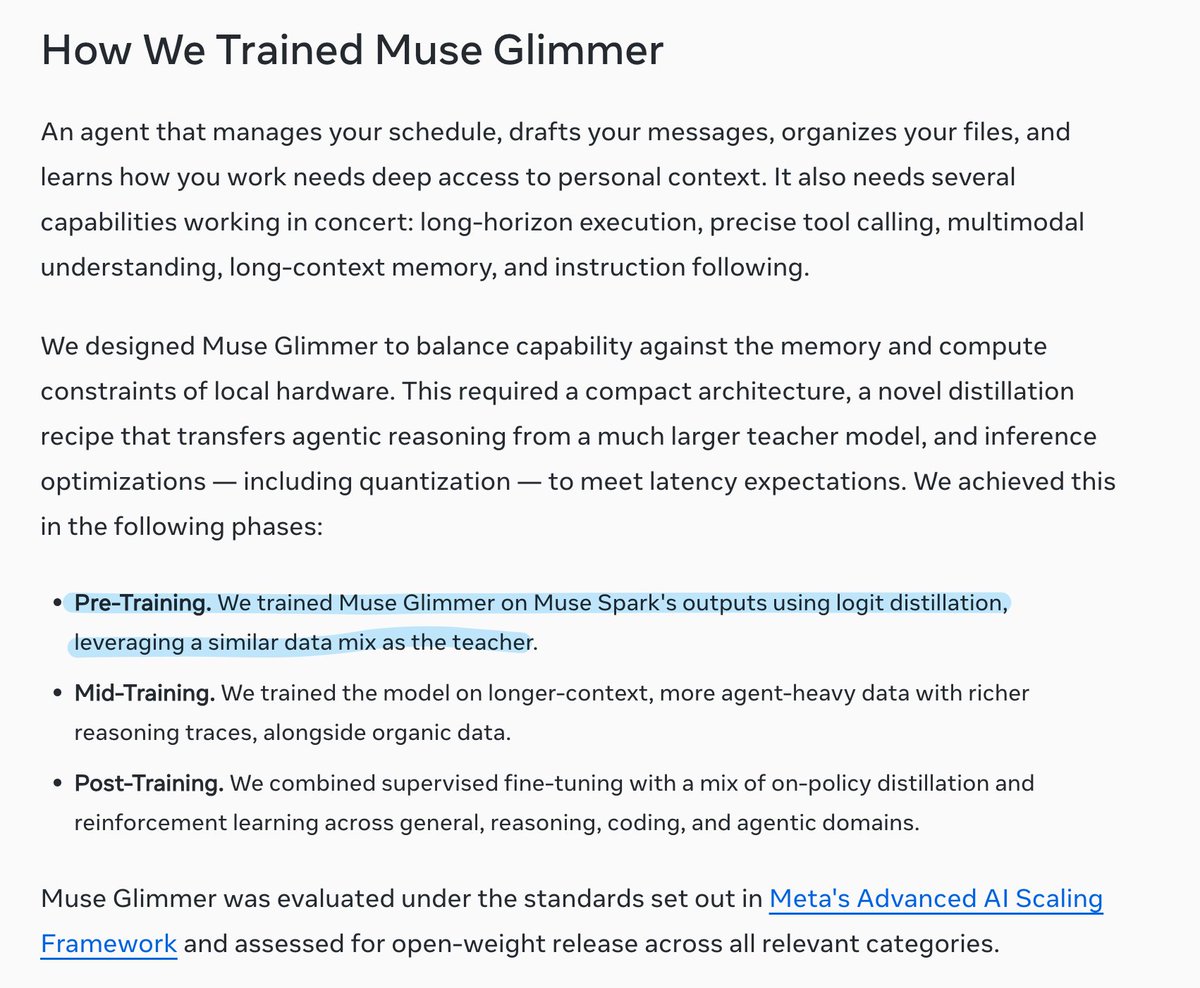
X post · Benchmarks & research· ♥ 464
 ChatForm
 Tgmlabs