shipwithmuse

Entries matching “dgx-spark”

17 builds · page 1 of 1

kwindla

@kwindla

Weekend project: play chess with Muse Spark running on a DGX Spark with code Muse Spark wrote. Setup: - projector - HDMI, camera, mic, and display server (Raspberry Pi) - pipecat bot (DGX Spark) - vision pipeline (RTX 5090) - coding agents running on the Pi, the DGX

X post · Games & 3D★ Pick· ♥ 27

Voice chess on a projector with Muse Spark

@vcruz305

@vcruz305

Tested SGLang and vLLM launch recipes for an NVFP4 export of a Hermes-agentic fine-tune of Muse-Glimmer-30B on NVIDIA DGX Spark (GB10).

GitHub · Local & open models

Hermes-agentic Glimmer NVFP4 on DGX Spark

@homerquan

@homerquan

A start/stop/status launcher that serves the NVFP4 Muse Glimmer 30B checkpoint on NVIDIA DGX Spark with vLLM, Glimmer's reasoning and tool parsers, and its DFlash speculative decoder.

GitHub · Local & open models· ★ 2

Muse Glimmer launcher for DGX Spark

@chishiki37

@chishiki37

Benchmark reports on Muse-Glimmer-30B on NVIDIA DGX Spark covering BF16 to Q4 to DFlash (a 10x speedup) and NVFP4 via SGLang, plus a head-to-head against Qwen3.6-27B.

GitHub · Benchmarks & research

Muse Glimmer optimization reports on DGX Spark

@r0b0tlab

@r0b0tlab

Reproducible native NVFP4 serving of Muse Glimmer 30B on one DGX Spark (GB10) with unmerged vLLM support: about 10.3 tok/s single-stream versus 4.2 for BF16, 52.5 tok/s at c16, and 131K context checked with needle-in-a-haystack tests.

GitHub · Local & open models

Muse Glimmer 30B NVFP4 on a single DGX Spark

@sxuff

@sxuff

A pinned llama.cpp recipe for Muse Glimmer 30B on one NVIDIA GB10 that verifies Meta's official GGUFs by SHA-256 and reproduces text, tool-call, coding, vision and throughput checks.

GitHub · Local & open models· ★ 1

Measured Muse Glimmer recipe for DGX Spark

LMSYS Org

@lmsysorg

@AIatMeta's Muse Glimmer (30B dense, open-weights) launches with SGLang day-0 support. We got ~230 tok/s on a single RTX 5090, with NVFP4 + DFlash on. It also works out of the box on @NVIDIAAIDev RTX Pro 6000, DGX Spark, and MLX for Mac. Speed and reliability have always been

X post · Local & open models· ♥ 129

SGLang serves Glimmer at ~230 tok/s on one RTX 5090

filipe

@filicroval

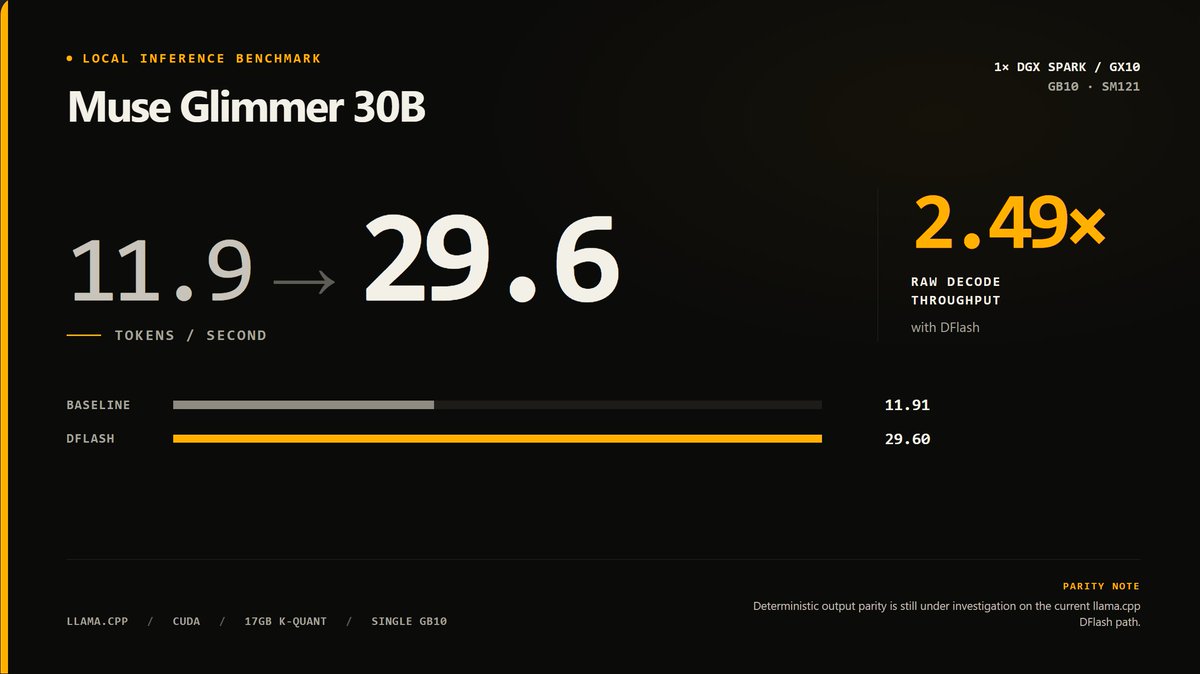
got Muse Glimmer 30B running on a single DGX Spark / GX10 at 29.6 tok/s with DFlash, up from 11.9 tok/s baseline, 2.49× raw decode throughput. packaged the whole thing into a reproducible GB10 recipe: - pinned weights + SHA-256s - llama.cpp compiled for GB10 / SM121 - baseline

X post · Local & open models· ♥ 5

Glimmer GB10 recipe at 29.6 tok/s

N

developer.nvidia.com

developer.nvidia.com

NVIDIA's technical blog reports Muse Glimmer serving over 20K tokens/sec on a single Blackwell Ultra GPU and covers RTX 5090, DGX Spark, DGX Station and Jetson deployments.

U

mr_il

u/mr_il

My fun weekend project was to try to make the new Muse Glimmer 30B work with a longer context, deciding to go for 512k first. I had expected the usual YaRN shenanigans and maybe a LoRA. I couldn't have been wrong more. Upon closer look, Glimmer turned out to be rather unusual architecturally. The thing that make long-context adaptations painful in other models, full attention layers with token position encoding, it simply not there. Instead, only 2048 tokens-wide SWA layers have RoPE, and full GQA attention layers have no position encoding at all. It appears the model is trained to work with long-distance token relationships inferred from the context and SWA layers. It's a rather bold architecture bet, but it seems Meta managed to pull it off. As a result, the model architecture appears to be uniquely suited for context extension by simple mechanical means. To change model context length from stock 128k to, say, 512k, you need only to change “max_position_embeddings” config setting from 131072 to 524288. What confuses other models, like Qwen3.5 family, Glimmer just takes into its stride. I spent close to 70h of compute on DGX Spark to test stock model with extended context on a

Reddit post · Local & open models★ Pick

Muse Glimmer 30B stretched to 512K context

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

Ryan | Intelligence Engineer

@RyanIntEngineer

I just built and validated a complete Muse Glimmer deployment for one DGX Spark. I didn’t make another quant—I integrated the available pieces into a pinned, verified, DFlash-accelerated, tool-capable, reboot-durable stack that actually works in OWUI.

X post · Local & open models· ♥ 4

Reboot-durable Glimmer stack on DGX Spark

@kenhuangus

@kenhuangus

Files from a working DeepSeek Harness session against Muse Glimmer 30B served by Ollama on a DGX Spark, including a sample agentic security project that queries an AST call graph.

@airawatraj

@airawatraj

Inference tuning notes for serving Muse Glimmer 30B NVFP4 with DFlash on a single NVIDIA DGX Spark as a consistent agent backend; the repo reports 27.5 tok/s average and 90/100 on its tool eval with 128K context.

GitHub · Local & open models

Muse Glimmer NVFP4 on DGX Spark

@lobanov

@lobanov

An effort to make Muse Glimmer 30B actually use a 512k-token context (4x native) as a ~17GB GGUF in 32GB VRAM, trained on DGX Spark and evaluated with RULER-style retrieval tests.

GitHub · Local & open models· ★ 1

Muse Glimmer 512k context adaptation

U

StartupTim

u/StartupTim

Heeeey all! I just completed some fun tests with Muse Glimmer, I thought I'd let you know. In fact, the summary below was written by Muse itself! I ran a 2× DGX Spark cluster and got Meta's day-old Muse Glimmer 30B running the day after release — then pushed its context from the trained 131K all the way to 1M with YaRN, verifying retrieval at every rung. Sharing config + results since the "131,072+" hint in the model card turned out to be very real. Setup • Hardware: 2× NVIDIA DGX Spark (GB10, 128 GB unified each, ~273 GB/s), ConnectX-7 direct link between them • Engine: llama.cpp master (day-1 muse_glimmer support), built from source with CUDA sm_121 + GGML_RPC • Model: official Muse-Glimmer-30B-GGUF K-Quant-Dynamic (~18.3 GiB) + official mmproj (vision) + official DFlash drafter • Spec decode: --spec-type draft-dflash --spec-draft-n-max 15 (block-diffusion drafter) • Context extension: --rope-scaling yarn --rope-scale <2/4/8> --yarn-orig-ctx 131072 plus --override-kv muse-glimmer.context_length=int:<N> (llama.cpp caps at trained length otherwise) • Yes, we also ran it split across both Sparks with llama.cpp RPC — no reason beyond liking to cluster things for fun. Our daily dri

Reddit post · Local & open models

Muse Glimmer at 1M context on 2x DGX Spark

SGLang

@sgl_project

SGLang is honored to provide day-0 support for @AIatMeta's Muse Glimmer. ~230 tok/s on a single RTX 5090 with NVFP4 + DFlash on, and it runs out of the box on @NVIDIAAI RTX PRO 6000, DGX Spark, and Apple Silicon via MLX. Huge thanks to the NVIDIA and Meta teams for the

X post · Local & open models· ♥ 95

SGLang day-0 serving for Glimmer

Your product

Sponsored

Put your logo, a line of copy and an image right here, between the builds Muse developers come to read. Same size as a post.

$100/week

Put your product here

Shown every 12 builds · on every catalog page

@MiaAI-Lab

@MiaAI-Lab

A one-script vLLM setup that serves the roughly 19 GB NVFP4 Muse Glimmer 30B with its vision encoder kept, DFlash speculative decoding using the official drafter head, and up to 256K context on GB10, RTX 5090 or RTX PRO 6000.

GitHub · Local & open models· ★ 8

Muse Glimmer 30B NVFP4 for DGX Spark and RTX 5090