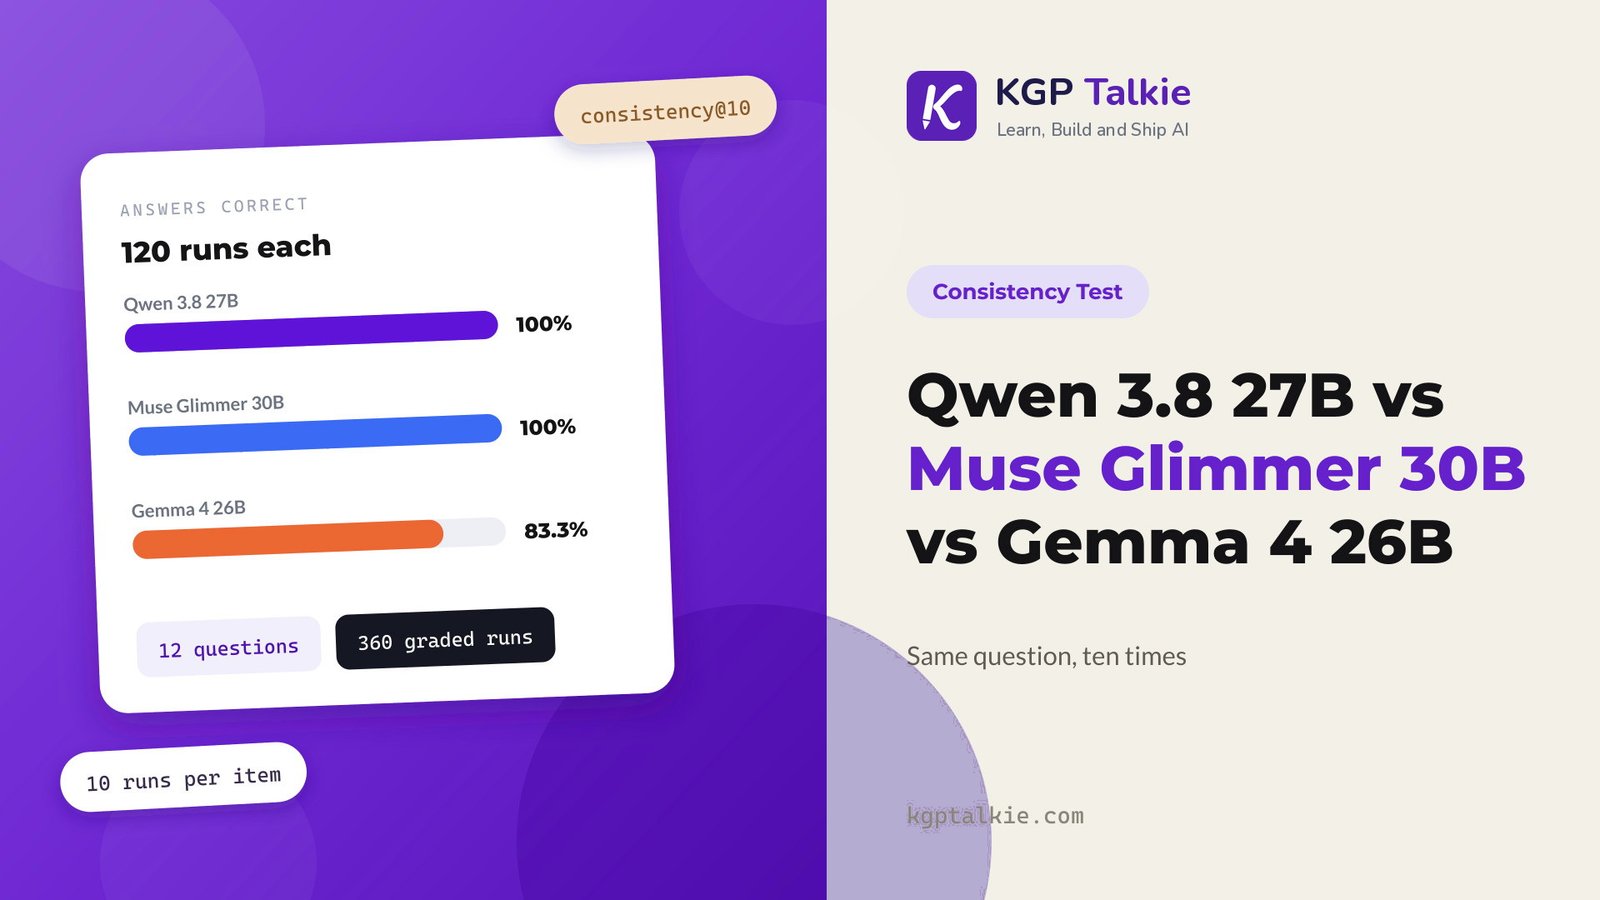
KGP Talkie asked Qwen 3.8 27B, Muse Glimmer 30B and Gemma 4 26B the same twelve questions ten times each to see which answers the same way twice.
Resource · Benchmarks & research
2 builds · page 1 of 1
KGP Talkie asked Qwen 3.8 27B, Muse Glimmer 30B and Gemma 4 26B the same twelve questions ten times each to see which answers the same way twice.
Resource · Benchmarks & research
Inference tuning notes for serving Muse Glimmer 30B NVFP4 with DFlash on a single NVIDIA DGX Spark as a consistent agent backend; the repo reports 27.5 tok/s average and 90/100 on its tool eval with 128K context.
GitHub · Local & open models

 ChatForm
 Tgmlabs